Published October 6, 2026. Details are as described by the original poster; we have not reproduced the benchmark.
Can an iPhone act as a second GPU for a MacBook?
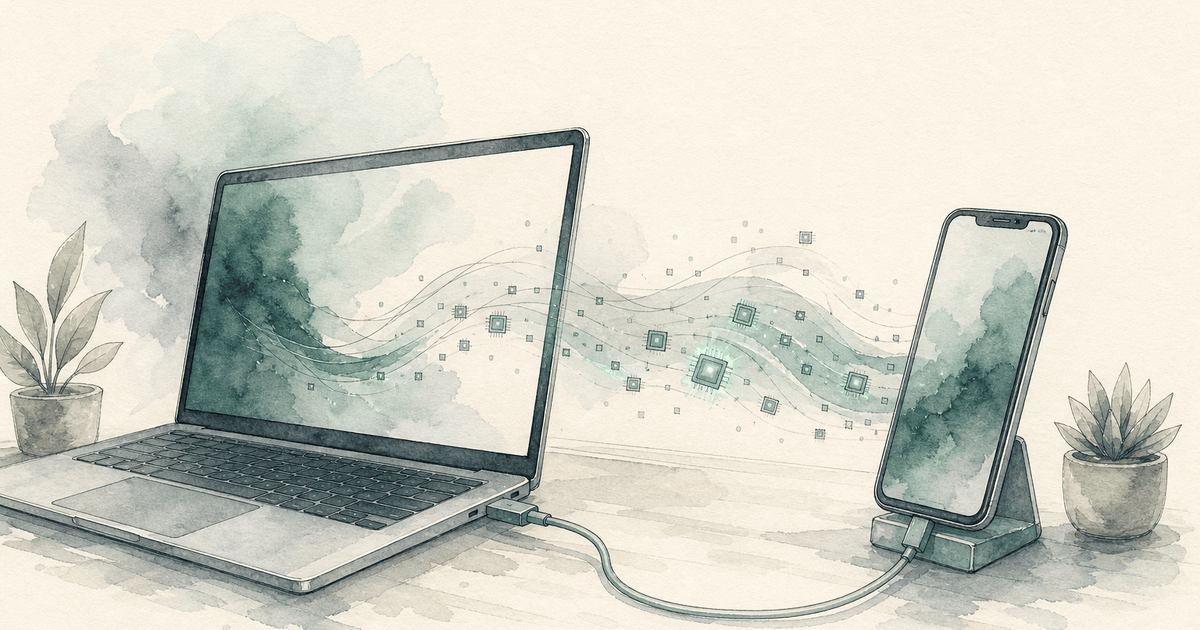
Yes, for some AI workloads. Reddit user StayLameBro offloaded part of a Qwen 3.8 27B model from a 24 GB M4 Pro MacBook to an iPhone 17 Pro Max and reported 29-44% faster prefill (the prompt-processing stage). The phone adds memory and compute, so a model that barely fits on the laptop runs with more headroom.
- The problem: a 27B model is tight on a 24 GB laptop.
- The trick: split the model's layers across two Apple devices and pass activations between them.
- The gain: 29-44% faster prefill, per the poster.
- The catch: it is an experiment, not a product. Link speed and phone thermals limit it.
The Reddit thread: r/LocalLLaMA: “I made my iPhone a second GPU for my 24 GB M4 Pro MacBook” (about 920 upvotes and 200 comments).
How does splitting a model across devices work?
A language model is a stack of layers. Normally all of them sit in one device's memory. In pipeline-split inference, the first device runs the first chunk of layers, sends the intermediate result to the second device, which runs the rest. Each device only needs memory for its own share.
The hard part is the connection. Every token has to cross it, so a slow link can erase the gain. That is why the speedup showed up mainly in prefill, where large batches of work move at once.
Prefill vs generation: why the difference matters
| Stage | What happens | Bottleneck | Who feels it |
|---|
| Prefill | The model reads your whole prompt and documents | Raw compute | Anyone pasting long documents or code |
| Generation | The model writes the answer token by token | Memory bandwidth | Everyone, on every reply |
Apple has been adding matrix acceleration to recent chips, and reviewers have measured large prefill gains on newer Apple silicon (MacStories). Using the phone's chip for extra prefill compute fits that trend.
Ways to run a bigger model than your machine fits
| Option | Cost | Speed | Difficulty |
|---|
| Quantize the model (smaller numbers) | Free | Faster, slight quality loss | Easy |
| Use a smaller model | Free | Fast | Easy |
| Split across your own devices | Free if you own them | Depends on the link | Hard |
| Buy more memory | High, and rising (memory prices are climbing) | Best local option | Easy |
| Use a cloud API | Pay per use | Fast | Easy |
Should a small business run AI locally?
Local AI is right when data truly cannot leave your machines, or when you run the same simple task at very high volume. For most small businesses it is the wrong first step: the work is in connecting AI to email, CRM and phone systems, not in squeezing a model onto a laptop.
A practical rule: start with a hosted model inside a workflow with approvals, measure what it does on your real tasks, and only move steps to local models once you know which ones are worth it.
Where Dooza fits
Dooza builds AI agents that connect to your existing tools (1,000+ app integrations) and picks the right model for each step, hosted or private, so you get the result without managing hardware.
Dooza is an AI-native company that builds AI products and services for small businesses, from the Dooza Workforce app to the Dooza Agents platform. A Dooza engineer scopes your pilot on a free 30-minute call, and every product starts with a refundable pilot: 100% refund within 14 days. Book a free pilot call or see pricing.
Ready to Start Your Pilot?
Automate your business with AI employees that work 24/7. Start with a refundable pilot: 100% refund within 14 days.